ClusterWareAI™
AI factory platform operating system software that unifies and automates cluster deployment and management — simplifying operations, streamlining administration and optimising performance.
With deep expertise at the intersection of AI infrastructure and memory solutions, Penguin Solutions helps you deploy and scale AI with superior token economics, measurable ROI and greater operational efficiency.
For nearly three decades Penguin Solutions has built the expertise to help customers turn AI investments into business outcomes. Their designation as an NVIDIA AI Factory Specialized Partner reflects proven experience designing, building, deploying and operating NVIDIA-based AI factory infrastructure at scale.
A platform that combines differentiated products and services with industry-leading partner technologies, so you can confidently deploy and scale AI workloads with speed and precision.
AI factory platform operating system software that unifies and automates cluster deployment and management — simplifying operations, streamlining administration and optimising performance.
Memory solutions designed specifically for data centres and AI inference. Together they optimise performance, improve efficiency and support the growing demand for inference and agentic AI.
Advanced computing systems and infrastructure elements optimised for AI workloads. Built for scalability and performance across AI training, inference and data-intensive applications.
Validated AI factory reference designs for scalable full-stack AI training and inference — accelerating deployment and scaling efficiently from hundreds to over 16,000 GPU clusters.
Expert support across the full AI lifecycle — design, build, deployment and managed services — helping you confidently deploy, optimise and scale AI environments.
Deep expertise in designing, building, deploying and managing AI data centres — enabling some of the world's most sophisticated workloads.
Accelerate time to value by basing system architectures on a proven set of designs validated at scale in numerous production deployments.
Achieve high rates of system stability with in-factory experts who integrate and validate every component — rack integration, network configuration and burn-in testing.
Drive on-site installations with coordination of data centre staff, storage partners and cooling providers, using ClusterWareAI™ to validate production readiness.
Assure production readiness and change management with a certified NVIDIA DGX Managed Services provider offering a full set of end-to-end services.
Three product families spanning AI infrastructure, always-on fault tolerant computing and specialty memory.
Validated reference designs and cluster software that turn bare metal into a production AI factory.
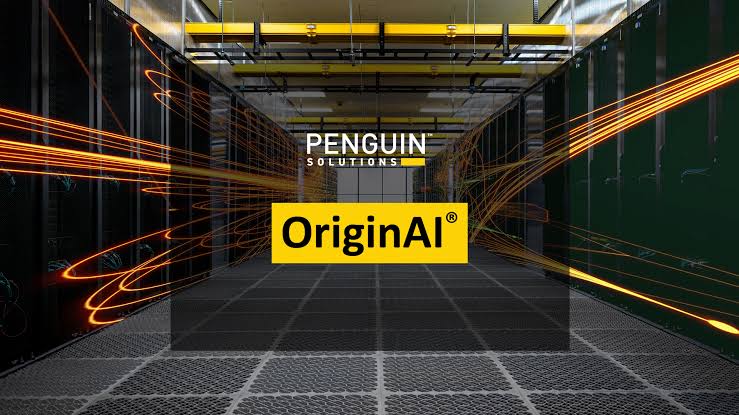
AI factory infrastructure built on proven, pre-defined architectures that scale from hundreds to over 16,000 GPU clusters, integrated with cluster management software and expert services.
Request a quote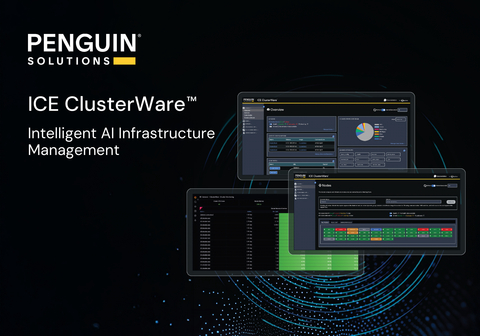
Transforms bare-metal hardware, network and software resources into high-performance cluster environments, reducing administration complexity and optimising resource use.
Request a quote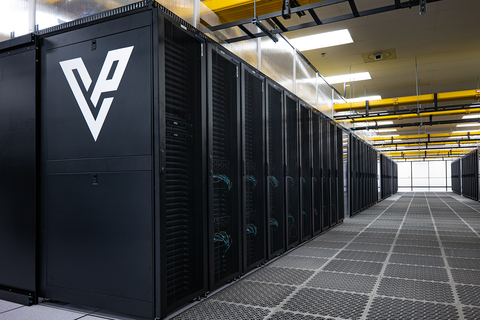
Large NVIDIA DGX clusters with high-speed InfiniBand networking and optimised storage, backed by deep relationships with most storage vendors for bespoke solutions.
Request a quoteStratus platforms that run complex software stacks at 99.99999% availability — no downtime, no data loss.
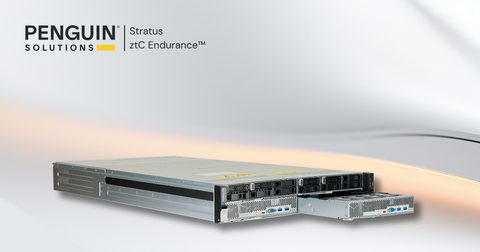
A family of computing platforms enabling intelligent, predictive fault tolerance and 99.99999% availability, combining built-in redundancy with proactive health monitoring.
Request a quote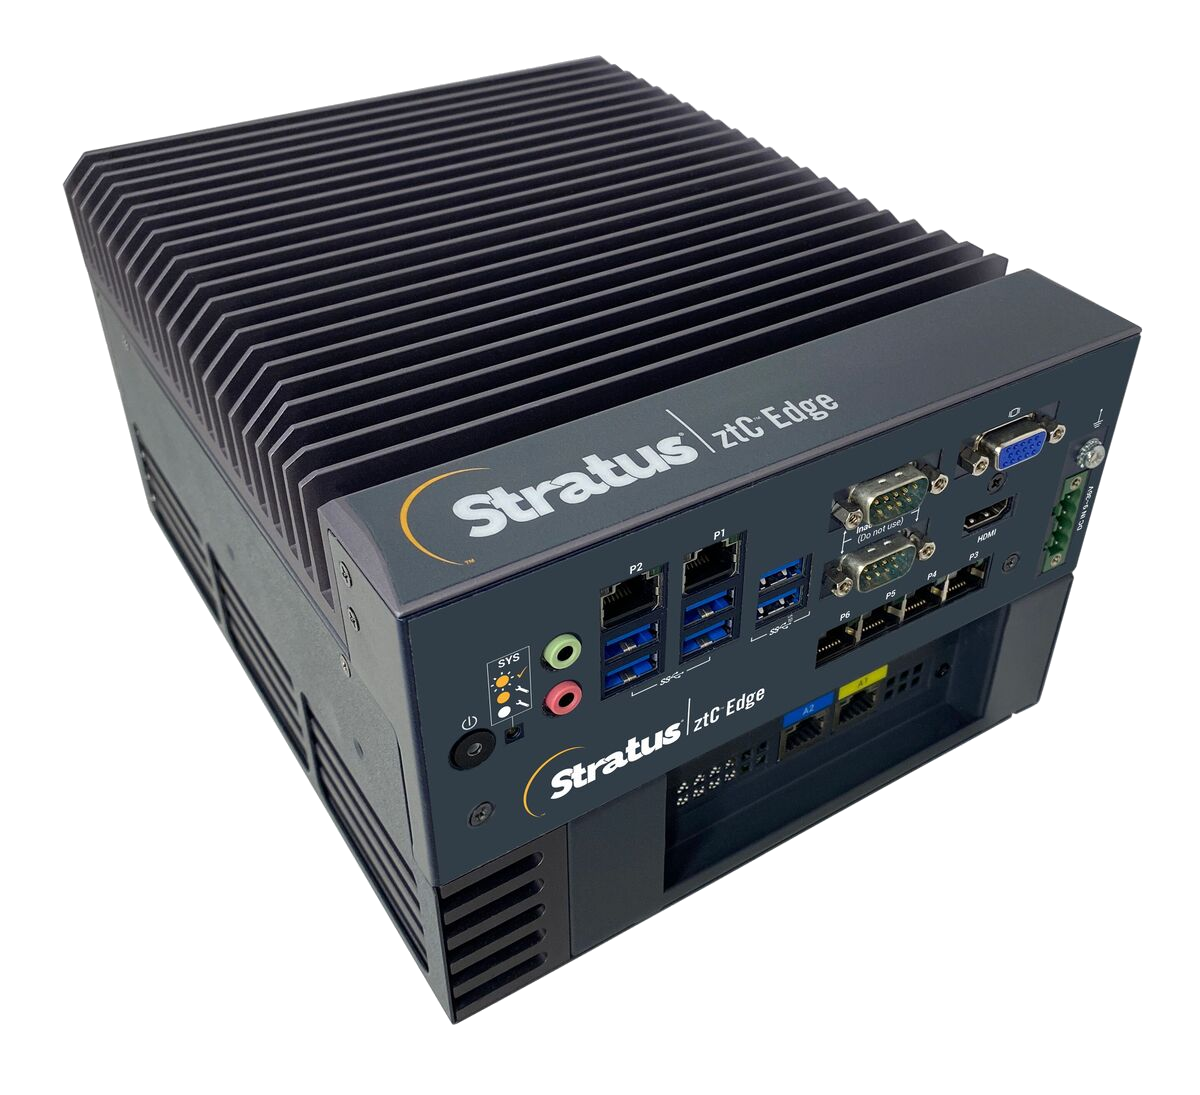
A secure, rugged, highly automated platform for the edge of corporate networks. Self-protecting and self-monitoring features drastically reduce unplanned downtime.
Request a quote
Software that pairs two servers via virtualisation to create protected, replicated VMs in a single operating environment — continuous availability without specialised hardware.
Request a quoteSpecialty memory built on CXL, DRAM and Flash to accelerate data centre and inference workloads.
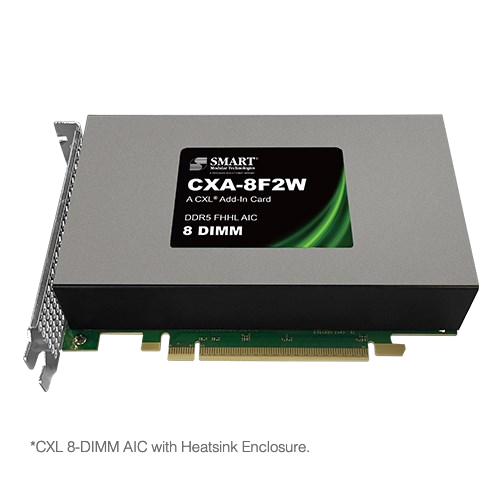
Compute Express Link enables data centres, cloud services and HPC providers to expand memory for intensive computing easily and cost-effectively.
Request a quote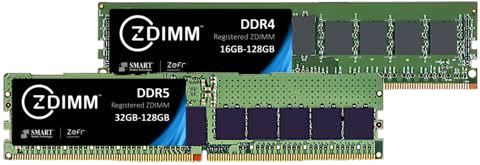
Ultra-high reliability modules ideal for data centres, hyperscalers and HPC platforms running large memory applications that require maximum compute availability.
Request a quote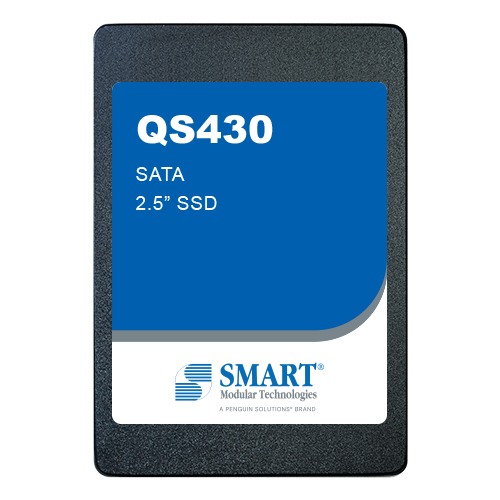
Next-generation SSDs designed to meet the stringent demands placed on storage in hyperscaler, hyper-converged, enterprise and edge data centres.
Request a quoteVirtual Graffiti Australia can scope, quote and source the full Penguin Solutions stack — from OriginAI clusters and ClusterWareAI software to Stratus fault tolerant platforms and specialty memory.